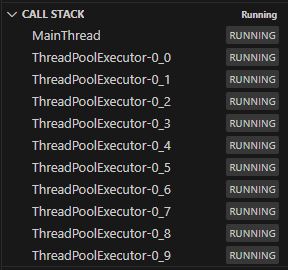
We will attempt to re-write the same code using threading, specifically concurrent.futures.ThreadPoolExecutor which offers a higher level interface to push tasks to a background thread without blocking execution of the calling thread, while still being able to retrieve their results when needed.
For our retry strategy, we use tenacity – a general-purpose retrying library to simplify the task of adding retry behavior to just about anything. pip install tenacity
# Retry strategy
@retry(stop=stop_after_attempt(3), wait=wait_exponential(multiplier=1, min=2, max=10), retry=retry_if_exception_type(requests.RequestException))
def download_file(url):
    filename = os.path.join(DOWNLOAD_DIR, os.path.basename(url))
    response = requests.get(url, stream=True)
    response.raise_for_status()
    with open(filename, 'wb') as f:
        for chunk in response.iter_content(chunk_size=8192):
            f.write(chunk)
    return url
@retry(stop=stop_after_attempt(3), wait=wait_exponential(multiplier=1, min=2, max=10), retry=retry_if_exception_type(requests.RequestException)): Retries the download up to 3 times, waiting exponentially between attempts (2 seconds minimum and 10 seconds maximum), and only retries on requests.RequestException.
main(urls, max_workers=10) manages the concurrent downloading.
Uses a ThreadPoolExecutor with a maximum of max_workers threads.
Submits each URL to the thread pool for downloading.
Waits for each future to complete and collect results.
Putting it all together
import concurrent.futures
import requests
import os
import logging
from tenacity import retry, stop_after_attempt, wait_exponential, retry_if_exception_type

# Directory to save the downloaded files
DOWNLOAD_DIR = 'downloads'
os.makedirs(DOWNLOAD_DIR, exist_ok=True)

# Configure logging
logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)

# Retry strategy
@retry(stop=stop_after_attempt(3), wait=wait_exponential(multiplier=1, min=2, max=10), retry=retry_if_exception_type(requests.RequestException))
def download_file(url):
    filename = os.path.join(DOWNLOAD_DIR, os.path.basename(url))
    response = requests.get(url, stream=True)
    response.raise_for_status()
    with open(filename, 'wb') as f:
        for chunk in response.iter_content(chunk_size=8192):
            f.write(chunk)
    return url

def main(urls, max_workers=10):
    with concurrent.futures.ThreadPoolExecutor(max_workers=max_workers) as executor:
        futures = {executor.submit(download_file, url): url for url in urls}
        for future in concurrent.futures.as_completed(futures):
            url = futures[future]
            try:
                result = future.result()
                successful_downloads.append(result)
            except Exception as e:
                failed_downloads.append(url)

# List of URLs to download
urls = [
    "https://photojournal.jpl.nasa.gov/jpeg/PIA00074.jpg",
    "https://photojournal.jpl.nasa.gov/jpeg/PIA00076.jpg",
    "https://photojournal.jpl.nasa.gov/vjpeg/PIA00114.jpg",
]

# Run the main function
if __name__ == '__main__':
    successful_downloads, failed_downloads = [], []
    main(urls)
    summary = f"""
**************** Summary ****************
✔️  Successfully downloaded {len(successful_downloads)}/{len(urls)} file(s).
{successful_downloads}

❌  Failed to downloaded {len(failed_downloads)} file(s).
{failed_downloads}
**************** Summary ****************
"""
    logger.info(summary)